EKS Pod Scaling
CloudNet 팀의 2026년 AWS EKS Workshop Study 4기 3주차 학습 내용을 담고 있습니다.
1. 1. Kubernetes의 Scaling 기법
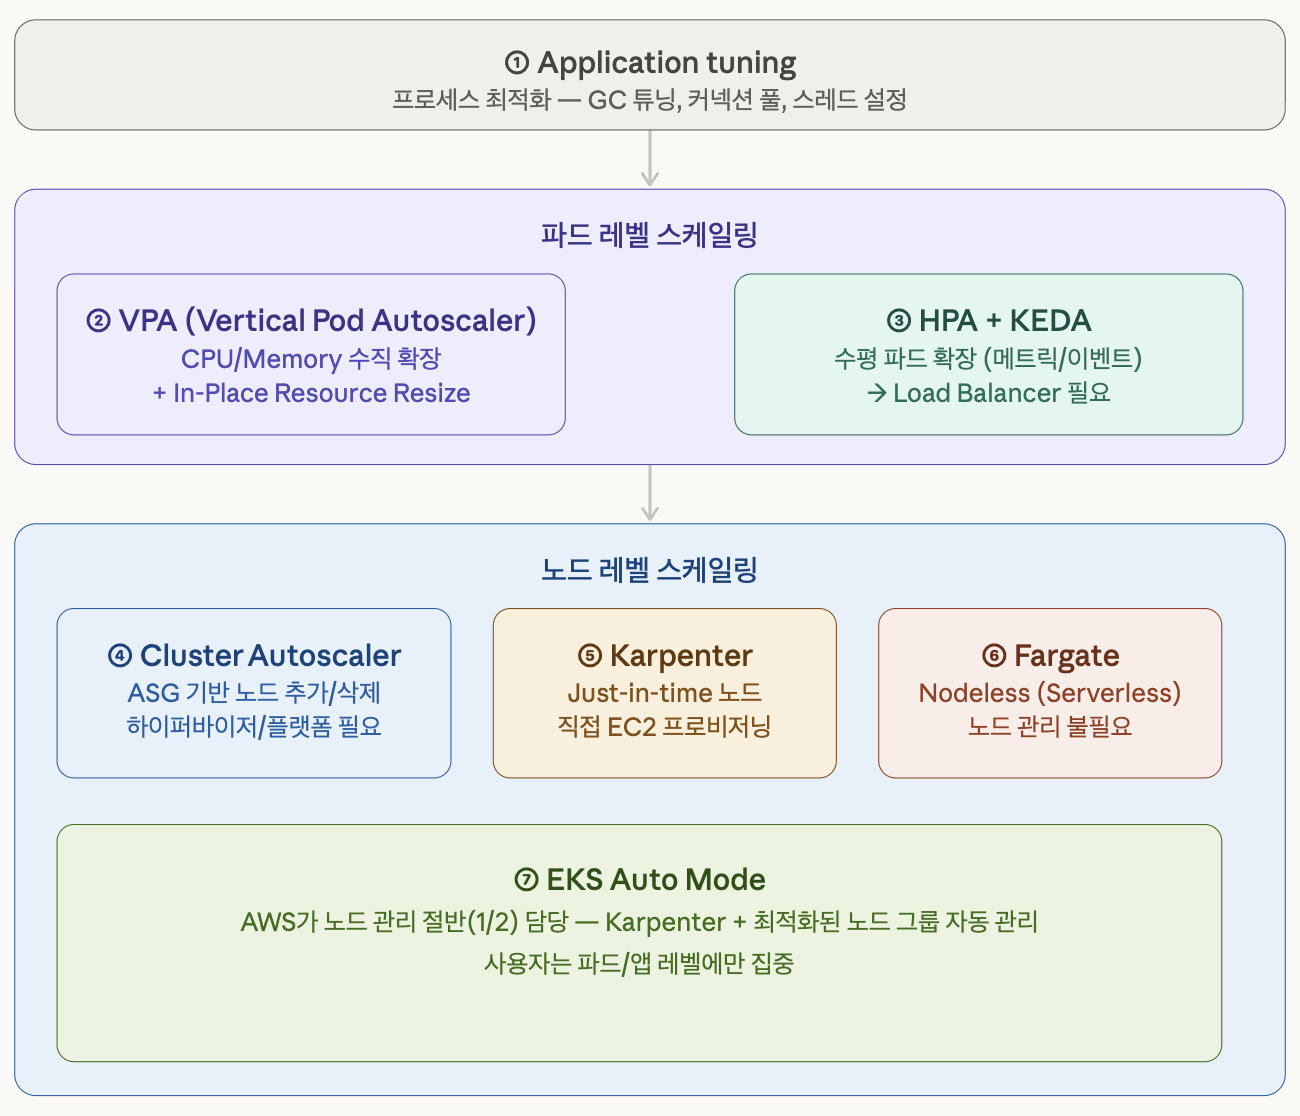
AWS EKS 스케일링은 크게 파드 레벨과 노드 레벨로 나눌 수 있습니다.
애플리케이션 병목이 해결 되지 않은 상태에서 파드와 노드만 스케일링한다면 인프라 비용이 비효율적으로 증가하게 됩니다. 트래픽 증가가 예상되는 경우 스케일링 작업 이전, 진행되는 이벤트의 성격에 맞게 애플리케이션 튜닝 작업을 진행하는 것이 좋습니다.
- 파드 레벨 스케일링
- VPA(Vertical Pod Autoscaler): 기존 파드에 CPU/Memory를 더 많이 주는 방식으로
requests와limits값을 자동으로 조정 - HPA(Horizontal Pod Autoscaler):
kubectl top이 수집하는 CPU/Memory 메트릭 기반 파드 수 조정 - HPA + KEDA: 특정 이벤트 기반으로 파드 수 조정
- CPA(Cluster Propotional Autoscaler): 클러스터 노드 수 또는 코어 수에 비례해 특정 워크로드의 파드 수를 조정
- VPA(Vertical Pod Autoscaler): 기존 파드에 CPU/Memory를 더 많이 주는 방식으로
-
노드 레벨 스케일링
- CA/CAS(Cluster Autoscaler): AWS의 Auto Scaling Group을 제어하여 파드 Pending 상태 또는 노드 활용률에 따라 노드를 동적으로 추가/삭제
- Karpenter: Just-in-Time Nodes, EC2 Fleet API를 직접 호출하여 노드 프로비저닝이 빠르며 파드 요구사항에 따라 실시간으로 최적의 노드 타입 할당
- 노드 그룹 자동관리:
- Fargate: 노드를 전혀 관리하지 않고 파드 단위로 인프라를 프로비저닝하는 방식, 파드 1개 = Firecracker 기반 전용 마이크로 VM
- EKS Auto Model: AWS가 노드 관리의 절반을 담당
-
참고자료
- EKS 스케일링 전략 종합 가이드 Link
- Hands-on 코드 자료: https://github.com/gasida/aews.git
2. HPA(Horizontal Pod Autoscaler)
HPA는 kube-controller-manager에 내장된 쿠버네티스의 네이티브 컨트롤러입니다.
파드의 리소스 메트릭 관찰을 통해 .spec.replicas를 조정하여 Deployment, Replicaset, Statefulset과 같은 scale 서브 리소스를 가진 리소스의 파드 복제본 수를 자동으로 조절하는 하는 역할을 합니다.
예: 50%의 CPU 사용률이 목표인 경우 평균 사용률이 50%를 초과할 때 복제본을 추가하고, 50% 이하로 떨어지면 복제본을 제거합니다.
2.1 동작 방식
HPA는 Kubernetes 컨트롤 플레인의 kube-controller-manager 내에서 실행되는 스레드입니다. 이 컨트롤러는 기본적으로 15초마다( --horizontal-pod-autoscaler-sync-period) 루프를 돌며 파드의 상태를 관측하고 스케일링 여부를 결정합니다.
전체적인 제어 루프는 관측(Observe) → 계산(Calculate) → 결정(Decide) → 실행(Act)의 4단계로 이루어집니다.
- 1단계(관측):
- HPA 컨트롤러가 Metrics API(metrics-server 또는 Custom Metrics API)에 질의하여 현재 설정된 메트릭 값을 수집
- CPU
averageUtilization기준 HPA의 사용률은 노드 전체 CPU가 아니라 대상 워크로드에 속한 모든 Ready 상태 파드의requests대비 사용률
- 2단계(계산):
- 수집된 메트릭을 기반으로 필요한 파드 수(Desired Replica)를 도출합니다.
- 3단계(결정):
- HPA가 Deployment의
replicas필드를 업데이트
- HPA가 Deployment의
- 4단계(배치):
- 컨트롤 플레인이 파드를 생성하여 노드에 배치
기타 제어 로직
- 다중 메트릭 처리:
- HPA는
autoscaling/v2에서 다중 메트릭을 사용할 수 있으며, 각 메트릭으로 계산된 desired replica 중 가장 큰 값을 선택합니다.
- HPA는
- 기타 설정(
behavior필드):- tolerance(허용 오차 설정): 목표치의 ±10% 이내의 변동은 무시
- scale-up/down stabilization window: 기본적으로 5분 이상 트래픽이 감소할 경우 파드 스케일 다운
2.2 스케일링 계산 공식
desired_replicas = ceil(current_replicas × (current_metric / target_metric))

예시:
    현재 replica: 5
    현재 CPU 평균 사용률: 80%
    목표 CPU 평균 사용률: 50%
    desired_replicas = ceil(5 × (80/50)) = ceil(5 × 1.6) = 8
    desired_replicas = 8
    → 파드 수 8개로 조정
2.3 메트릭 종류
| 메트릭 유형 (Type) | 대상 (Target) 평가 방식 (Metric Source) | 주요 활용 사례 | 수집 소스 및 비고 |
|---|---|---|---|
| Resource | Pod 내 컨테이너 리소스 사용량 (CPU, Memory) | 일반적인 시스템 부하 관리 (CPU 60% 이상 시 확장) | Metrics Server |
| Object | K8s의 특정 오브젝트 (예: Ingress, Service 등)메트릭 |
Ingress의 RPS(초당 요청 수)에 따른 스케일링 | Custom Metrics API (예: Prometheus Adapter) |
| Pods | 대상 모든 Pod의 전체 평균 | 앱 내부 TPS, 동시 접속자 수 평균 기반 확장 | Custom Metrics API (예: App 소스 내 Prometheus Exporter) |
| External | K8s 클러스터 외부 리소스 (SQS, Kafka 등) | 외부 메시지 큐 대기열 수에 따른 워커 확장 | External Metrics API (예: CloudWatch, Datadog, Kafka 등 외부 API) |
2.4 주의사항
- HPA CPU 스케일링은 pod spec의
resources.requests.cpu필드 기준으로 사용률을 계산하므로, HPA가 정상적으로 동작하려면 해당값이 설정되어야 합니다. - Ready 상태가 된 파드만 HPA 계산에 포함되므로, readinessProbe를 설정하여 준비되지 않은 파드가 트래픽을 받지 않도록 해야 합니다.
2.5 HPA 설정 예시
다중 메트릭 예시 YAML
‼️‼️ 여러 개의 메트릭이 정의되어 있을 경우, 각 메트릭 별로 필요한 Replicas 수를 계산한 뒤 그 중 가장 높은 값을 선택합니다.
apiVersion: autoscaling/v2
kind: HorizontalPodAutoscaler
metadata:
  name: advanced-hpa
spec:
  scaleTargetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: my-web-service
  minReplicas: 2
  maxReplicas: 20
  metrics:
  # [Resource] CPU 사용량이 평균 60%를 넘을 때
  - type: Resource
    resource:
      name: cpu
      target:
        type: Utilization
        averageUtilization: 60
  # [Object] Ingress의 초당 요청수가 1,000을 넘을 때
  - type: Object
    object:
      describedObject:
        kind: Ingress
        name: main-ingress
      metric:
        name: requests-per-second
      target:
        type: Value
        value: 1k
  # [Pods:] 각 파드별 '초당 처리 요청수'의 평균이 500개일 때
  # 모든 파드의 값을 합산해 현재 파드 수로 나눈 평균값을 타겟(500)과 비교합니다.
  - type: Pods
    pods:
      metric:
        name: http_requests_per_second
      target:
        type: AverageValue
        averageValue: 500
  # [External] 외부 메시지 큐(예: SQS)에 대기 메시지가 많을 때
  - type: External
    external:
      metric:
        name: queue_messages_ready
      target:
        type: AverageValue
        averageValue: 50
  # [External] AWS RDS CPU 사용률 기반 (CloudWatch Adapter 사용 시)
  - type: External
    external:
      metric:
        name: cloudwatch_rds_cpu_utilization_average
        selector:
          matchLabels:
            DBInstanceIdentifier: my-production-db
      target:
        type: Value
        value: 80  # RDS CPU가 80%를 넘으면 서버 확장 준비
  # [External] Datadog 지표 기반 (Datadog Cluster Agent 사용 시)
  # 예: 전체 시스템의 에러율(error_rate)이 높아질 때 확장
  - type: External
    external:
      metric:
        name: datadog.metric.my_app.request_error_rate
      target:
        type: Value
        value: 5   # 에러율이 5%를 넘으면 확장
  behavior:
    scaleUp:
      selectPolicy: Max # Max/Min/Disabled 중 선택, 기본값 Max
      stabilizationWindowSeconds: 0
      policies:
      - type: Percent
        value: 100 # 한 번에 현재 replica 수의 100% 만큼 스케일 아웃 가능
        periodSeconds: 15
    scaleDown:
      # 스케일인은 5분 대기 후 한 번에 최대 10%씩만
      stabilizationWindowSeconds: 300
      selectPolicy: Max
      policies:
      - type: Percent
        value: 10
        periodSeconds: 60
3. VPA (Vertical Pod Autoscaler)
VPA는 파드가 실제로 사용하는 자원 패턴을 분석하여 컨테이너의 requests와 limits 값을 자동으로 최적화합니다.
3.1 Requests vs Limits
VPA가 무엇을 조작하는지 이해하기 위해서는 먼저 쿠버네티스의 리소스 관리 기준인 requests와 limits의 차이를 알 필요가 있습니다.
-
Requests (요청량) = 스케줄러용
- 파드 초기 실행 시, 파드가 정상적으로 실행되기 위해 보장되어야 하는 최소한의 리소스를 요청하는 값입니다.
- kube-scheduler는 각 노드의 여유 리소스를 확인하고, 파드의
requests를 수용할 수 있는 노드에만 파드를 배치(스케줄링)합니다. - 초과시 동작: 파드가
Pending상태로 생성되지 않습니다. - HPA의 기준점: HPA에서 CPU 사용률을 50%로 설정했다면, 이 50%는 실제 노드의 전체 CPU가 아니라 파드의 CPU
requests값 대비 50%를 의미합니다.
-
Limits (제한량): 리소스 사용 상한선(cgroup용)
- 파드가 노드에 배치된 후 파드가 사용할 수 있는 리소스의 최대 한계치입니다. 이 값은 컨테이너 런타임을 통해 호스트 OS의 c은 비즈니스groups 설정으로 변환되어 커널이 리소스 사용을 통제합니다. 노드에 자원이 남더라도 파드는 이 설정값을 초과해서 사용할 수 없습니다.
- 초과 시 동작:
- CPU: CPU는 압축 가능한(Compressible) 리소스이므로 초과 시 컨테이너가 종료되지는 않습니다. 설정된 Limit 이상의 자원 사용 시 커널이 CPU 할당 시간을 제한합니다. 이로 인해 CPU Throttling이 발생하여 프로세스가 종료되지는 않지만 애플리케이션의 응답 속도가 느려집니다.
- Memory: 메모리는 압축할 수 없는(Incompressible) 리소스이므로, Limits를 초과하면 리눅스 커널은 시스템 전체가 마비되는 것을 막기 위해 파드를 강제 종료합니다. = OOMKilled (Out Of Memory) 상태가 됩니다.
Best Practice:
CPU는 Requests와 Limits를 동일하게 주어 Guaranteed QoS 클래스를 보장하거나 Limits를 아예 해제하기도 하지만, 메모리의 경우 메모리 누수로 인한 노드 전체의 장애를 막기 위해 Limits를 반드시 설정하는 것이 권장됩니다.
1. 일반적인 웹/API 서버 (Burstable): CPU Requests 설정 + CPU Limits 해제 + Memory Requests/Limits 동일하게 설정
2. 민감한 핵심 워크로드 (Guaranteed): CPU & Memory 모두 Requests = Limits 로 동일하게 설정
3.2 VPA 동작 방식
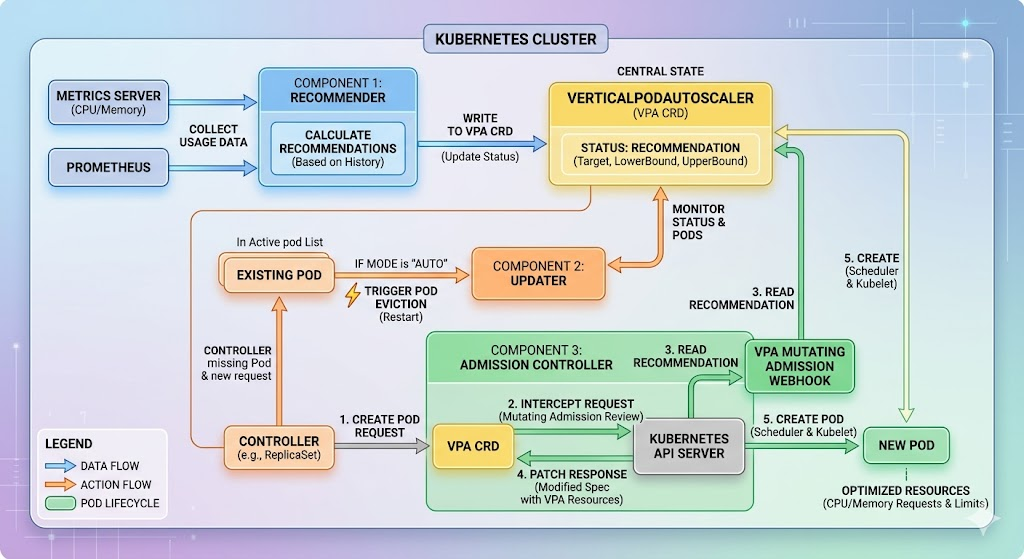
- 동작 방식:
- Recommender가 과거 리소스 사용 이력을 분석 → VerticalPodAutoscaler 오브젝트에 권장값 작성 → Updater가 파드를 재시작하면서 새 값 적용 → Admission Controller가 신규 파드 생성 시 권장값 자동 주입.
| 컴포넌트 | 주요 역할 | 데이터 소스 | 핵심 동작 |
|---|---|---|---|
| Recommender | 파드의 리소스 사용량 분석 및 최적의 권장량(CPU/Memory) 산출 | Metrics Server Prometheus |
계산된 권장값(Target, Min, Max)을 VPA CRD의 상태(Status) 필드에 지속적으로 기록 |
| Updater | 현재 파드의 할당량과 권장값의 차이를 모니터링하여 파드 재시작 유도 | VPA CRD (권장값) 현재 실행 중인 파드의 리소스 스펙 |
차이가 크고 모드가 Auto일 경우, 기존 파드를 축출(Evict)하여 상위 컨트롤러를 통한 재생성 유도 |
| Admission Controller (Mutating Webhook) |
새로 생성되는 파드의 생성 요청을 가로채어 최적화된 리소스 값을 자동 주입 | VPA CRD (최신 Target 권장값) | API 서버의 파드 생성 요청을 Intercept 후, 권장 리소스가 주입(Patch)된 스펙을 API 서버로 반환하여 파드 생성 |
3.3 VPA 업데이트 모드
Auto 모드와 InplaceOrRecreate는 상황에 따라 파드를 재시작할 수 있어 다운타임 발생의 위험이 있습니다. 프로덕션 환경에서는 Off, Initial을 사용하거나, 반드시 자동으로 스케일업이 수행되어야 한다면 파드를 여러 대 띄우고 PDB를 필수적으로 설정하는 것이 좋습니다.
Off모드- 권장사항만 제공
- 관리자가 수동으로 적용하거나, 외부 CD 툴 사용하여 롤링 업데이트 시 사용 가능
Initial모드- 파드가 처음 스케줄링 될 때 딱 한 번만 개입하여 권장값 주입
- 이미 실행되어 서비스 중인 파드는 권장값과 차이가 발생하더라도 절대 축출되지 않음
Auto모드- 초기 생성 시 권장값을 주입하고, 실행중인 파드 모두 VPA 권장값과 크게 차이 나면 파드를 축출하고 신규 파드 생성
InPlaceOrRecreate모드- 기존에는 리소스 변경 시 파드 재시작이 필수였으나, 1.33 GA 버전 이후 기능이 도입되어 재시작 없이 실행 중인 파드의 CPU/Memory를 변경 가능
- 1순위 동작 (In-place Update): 파드를 축출(Evict)하는 대신 Kubernetes API의
resize하위 리소스를 호출하여 컨테이너 런타임이 백그라운드에서 Linux cgroup 설정만 변경 - 2순위 동작 (Fallback to Recreate): 현재 파드가 떠 있는 노드에 리소스가 부족하거나, OS 제약으로 메모리를 줄이는 것이 불가한 경우 파드를 종료하고 새로운 노드에 생성
- CPU와 메모리만 In-place로 변경 가능, Windows 노드 미지원
3.4 VPA + HPA 함께 사용하기
HPA와 동시 사용 시 동일한 리소스 지표를 바라본다면 다음과 같은 충돌이 발생할 수 있습니다.
- targetCPUUtilizationPercentage 기반 HPA + VPA
- VPA가 CPU requests를 올리면 HPA의 스케일링 기준이 변경되어 스케일 인 발생 → 파드 수가 줄어들어 각 파드에 대한 부하 상승 → VPC가 다시 CPU Request 샹항 조정 → 무한 루프 발생
권장 사용 방법
- VPA를
updateMode: "Off", 또는updateMode: "Initial"설정으로 사용 - VPA와 HPA가 서로 다른 지표를 모니터링
예: VPA는 파드의 CPU/Memory 기반으로 Requests/Limits 최적화하고, HPA를 리소스 메트릭 대신 RPS, Active Connections, Queue length 또는 KEDA를 통한 이벤트 기반의 스케일 인/아웃 수행 - Goldilocks 사용
4. KEDA
KEDA(Kubernetes Event-Driven Autoscaling)는 리소스 사용량 대신, 외부 이벤트 소스의 메트릭(예: SQS의 큐 길이, 메시지 적재량 등)을 기반으로 파드를 스케일링하는 역할을 합니다.
HPA는 CPU/메모리를 기반으로 파드를 스케일링 하므로 메시지 큐에 100만 개가 쌓여있더라도 CPU 리소스 사용량이 적으면 파드 수를 늘리지 않습니다. KEDA + HPA를 사용 시 이벤트 기반으로 파드를 스케일링할 수 있습니다.
Scale to Zero: HPA는 최소 1개의 파드를 남겨둬야 하지만, KEDA는 이벤트가 없으면 파드를 0개로 완전히 줄였다가(
minReplicaCount=0), 이벤트가 들어오는 즉시 1개(또는 설정값)를 생성할 수 있습니다.
4.1 KEDA의 구조
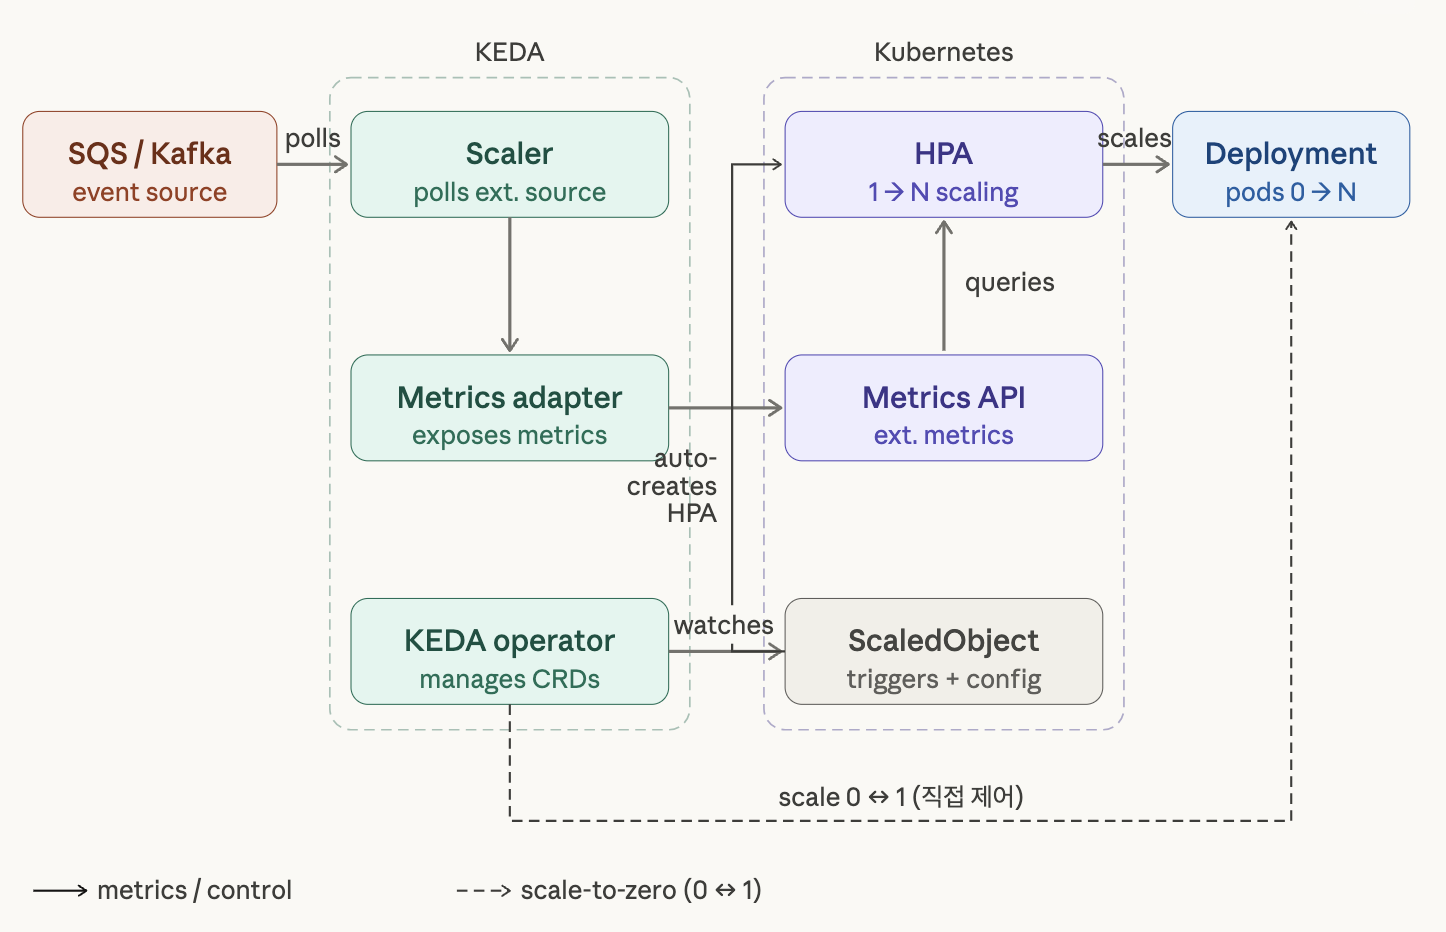
KEDA의 주요 세 가지 컴포넌트:
- KEDA Operator:
ScaledObject및ScaledJob과 같은 커스텀 리소스(CRD)를 감시하고 관리- 이벤트가 발생하지 않을 때 Deployment를 0으로 스케일링하거나, 첫 번째 이벤트가 들어왔을 때 1로 활성화하는 역할을 담당
- Metrics Adapter:
- 외부 이벤트 소스(SQS, Kafka, Prometheus 등)로부터 수집한 지표를 쿠버네티스 External Metrics API로 노출
- HPA는 이 어댑터를 통해 지표를 조회하여 1개 이상의 파드 상태에서 스케일링을 결정
- Scaler:
- 특정 외부 시스템과 통신하여 지표를 가져오는 어댑터 라이브러리
- AWS SQS, Azure Monitor, GCP Pub/Sub, Redis, Kafka, PostgreSQL 등 60개 이상의 스케일러 지원
4.2 ScaledObject vs ScaledJob
- ScaledObject: Deployment, StatefulSet 등을 스케일링할 때 사용합니다. 지속적으로 실행되어야 하는 워커 서비스에 적합합니다.
- ScaledJob: 각 이벤트마다 별도의 Kubernetes Job을 띄울 때 사용합니다. 긴 시간이 걸리는 배치 작업이나, 각 메시지마다 독립적인 실행 환경이 필요한 경우에 유리합니다.
4.3 활용 사례
- 배치/워커형 workload처럼 입력 이벤트가 쌓일 때만 많이 확장해야 하는 경우
- CPU는 낮지만 큐 깊이는 급격히 증가하는 비동기 처리 시스템
- 특정 시간대나 외부 시스템 상태에 따라 scale-up/down을 제어하고 싶은 경우
4.4 주의사항
- AWS 서비스와 연동할 때는 IRSA(IAM Roles for Service Accounts)를 사용합니다.
- 장기 실행 작업에서는 scale-down 시 현재 처리 중인 작업이 중단될 수 있으므로 종료 처리와
terminationGracePeriodSeconds를 함께 설계해야 합니다. - 메트릭 캐싱, polling interval, activation threshold를 적절히 조정해야 합니다.
- KEDA가 ScaledObject를 바탕으로 HPA를 자동 생성하므로 동일한 Deployment에 수동으로 HPA를 생성하면 충돌이 발생할 수 있습니다.
- 파드만 스케일링 하므로,
maxReplicaCount를 설정할 때 클러스터의 전체 노드 자원과 쿼터를 확인하지 않으면 노드 부족으로 인한 Pending 상태가 될 수 있습니다.
4.5 KEDA 설정 예시
apiVersion: keda.sh/v1alpha1
kind: ScaledObject
metadata:
  name: advanced-sqs-scaler
spec:
  scaleTargetRef:
    name: heavy-worker
  pollingInterval: 30  # 외부 소스를 확인하는 주기(초)
  cooldownPeriod:  300 # 마지막 이벤트 후 0으로 줄이기 전 대기 시간(초)
  idleReplicaCount: 0  # 이벤트 없을 시 유지할 파드 수
  minReplicaCount: 1   # (옵션) 0으로 줄이지 않고 최소 1개 유지할 경우
  maxReplicaCount: 100
  advanced:
    restoreToOriginalReplicaCount: true # ScaledObject 삭제 시 원래 replica 수로 복구
    horizontalPodAutoscalerConfig:
      behavior: # HPA 스케일링 속도 제어
        scaleDown:
          stabilizationWindowSeconds: 300
          policies:
          - type: Percent
            value: 10
            periodSeconds: 60
  triggers:
  - type: aws-sqs-queue
    authenticationRef:
      name: keda-aws-auth # TriggerAuthentication 리소스 참조
    metadata:
      queueURL: [https://sqs.ap-northeast-2.amazonaws.com/12345/my-queue](https://sqs.ap-northeast-2.amazonaws.com/12345/my-queue)
      queueLength: "5" # 메시지 5개당 파드 1개 추가 생성 시도
5. CPA(Cluster Proportional Autoscaler)
CPA는 클러스터의 총 코어 수 또는 노드 수에 비례해 대상 워크로드의 복제본 수를 자동 조정하는 오토스케일러입니다. CoreDNS처럼 클러스터 규모가 커질수록 처리량이 함께 증가하는 시스템 컴포넌트에 특히 적합합니다.
5.1 동작 방식
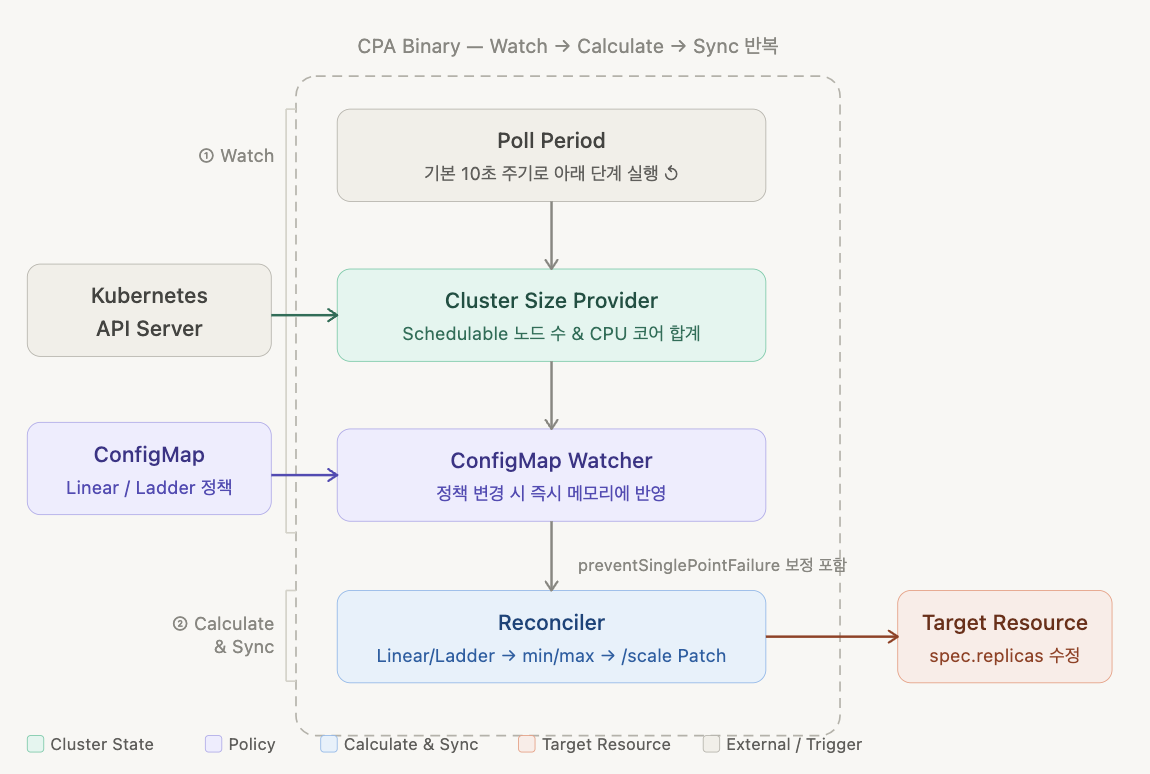
CPA Binary는 Deployment 객체로 kube-system 네임스페이스에 파드로 생성되며, 설정은 ConfigMap에 저장됩니다.
5.1.1 주요 컴포넌트
- Poll Period: 이벤트 기반이 아닌 Polling 방식으로 동작합니다. (기본값: 10초)
- ConfigMap Watcher: 사용자가 정의한 스케일링 정책이 담긴 ConfigMap을 감시합니다. 정책이 변경되면 즉시 메모리에 반영합니다.
- Cluster Size Provider: 쿠버네티스 API 서버를 호출하여 현재 클러스터의 정보(Schedulable Nodes,
- Reconciler: 현재 상태와 정책을 비교하여 최종적으로 유지해야 할 Target Replicas를 결정합니다.
5.1.2 CPA에 필요한 RBAC 요소
| 컴포넌트 | 설명 |
|---|---|
| ServiceAccount | CPA 파드가 API 서버 인증시 사용하는 계정 |
| ClusterRole | nodes를 get/list/watch 할 수 있는 권한과, 대상 리소스(예: deployments/scale)를 get/update 할 수 있는 권한 |
5.2 동작 모드
- 1. Linear Mode (선형 모드)
Linear 모드는 코어 기준과 노드 기준으로 각각 필요한 복제본 수를 계산한 뒤, 더 큰 값을 선택해 적용합니다. 각 기준 계산 시 올림을 적용하고, 마지막에 최소/최대 복제본 범위로 제한합니다.
가장 많이 사용되는 방식으로, 코어 수나 노드 수에 따라 일정한 비율로 파드를 늘립니다. 계산식은 다음과 같습니다.
Replicas = clamp(max(ceil(cores/coresPerReplica), ceil(nodes/nodesPerReplica)), min, max)
-
설정 변수:
coresPerReplica: 파드 1개당 할당될 코어 수 (예: 16코어당 파드 1개)nodesPerReplica: 파드 1개당 할당될 노드 수 (예: 2노드당 파드 1개)min: 최소 파드 수, 계산된 값이 min보다 작으면 min으로 제한 (가용성 관점에서 2 이상을 권장)max: 최대 파드 수, 계산된 값이 max보다 크면 max로 제한preventSinglePointFailure: 노드가 2개 이상일 때 파드도 최소 2개 이상 유지하도록 보정- 예시: 만약 nodesPerReplica가 2이고 현재 노드가 10대라면, CPA는 10 / 2 = 5개의 파드를 유지
-
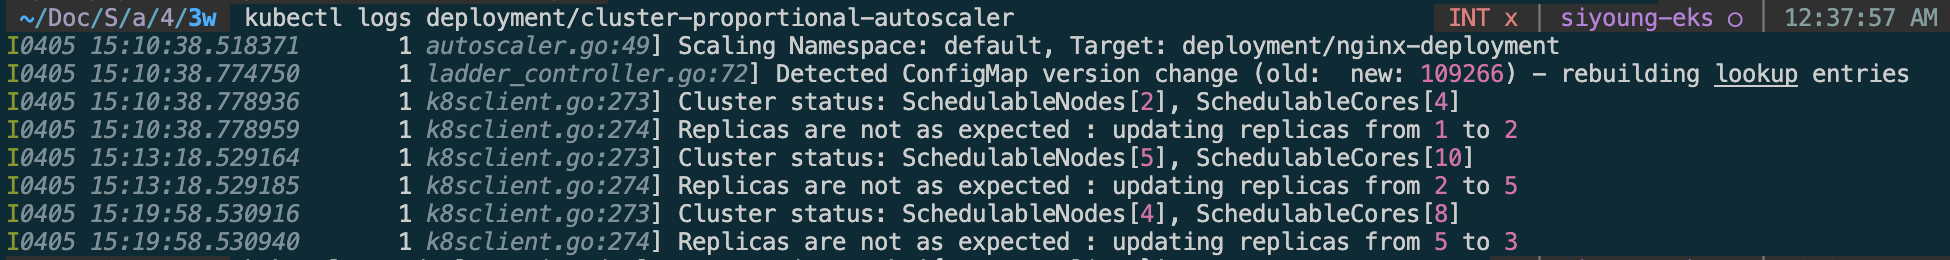
2. Ladder Mode (계단형 모드) 사전에 정의한 구간 표에 따라 파드 수를 계단식으로 결정하여 할당하는 방식입니다. 급격한 스케일의 변동을 줄이고 운영자가 의도한 단계별 확장 정책을 적용할 때 유용합니다.
-
설정 방식: 테이블 형태로 구간을 정의합니다.
- 노드 1~3개 → 파드 2개
- 노드 4~10개 → 파드 5개
- 노드 11개 이상 → 파드 10개
- 코어 수에 따라 파드 할당 예시
- 노드 수에 따라 파드 할당 예시
5.3 Hands-on
#
helm repo add cluster-proportional-autoscaler https://kubernetes-sigs.github.io/cluster-proportional-autoscaler
# CPA규칙을 설정하고 helm차트를 릴리즈 필요
helm upgrade --install cluster-proportional-autoscaler cluster-proportional-autoscaler/cluster-proportional-autoscaler
# nginx 디플로이먼트 배포
cat <<EOT > cpa-nginx.yaml
apiVersion: apps/v1
kind: Deployment
metadata:
name: nginx-deployment
spec:
replicas: 1
selector:
matchLabels:
app: nginx
template:
metadata:
labels:
app: nginx
spec:
containers:
- name: nginx
image: nginx:latest
resources:
limits:
cpu: "100m"
memory: "64Mi"
requests:
cpu: "100m"
memory: "64Mi"
ports:
- containerPort: 80
EOT
kubectl apply -f cpa-nginx.yaml
# CPA 규칙 설정
cat <<EOF > cpa-values.yaml
config:
ladder:
    nodesToReplicas:
      - [1, 1]
      - [2, 2]
      - [3, 3]
      - [4, 3]
      - [5, 5]
options:
namespace: default
target: "deployment/nginx-deployment"
EOF
kubectl describe cm cluster-proportional-autoscaler
# 모니터링
watch -d kubectl get pod
# helm 업그레이드
helm upgrade --install cluster-proportional-autoscaler -f cpa-values.yaml cluster-proportional-autoscaler/cluster-proportional-autoscaler
# 노드 5개로 증가
export ASG_NAME=$(aws autoscaling describe-auto-scaling-groups --query "AutoScalingGroups[? Tags[? (Key=='eks:cluster-name') && Value=='siyoung-eks']].AutoScalingGroupName" --output text)
aws autoscaling update-auto-scaling-group --auto-scaling-group-name ${ASG_NAME} --min-size 5 --desired-capacity 5 --max-size 5
aws autoscaling describe-auto-scaling-groups --query "AutoScalingGroups[? Tags[? (Key=='eks:cluster-name') && Value=='siyoung-eks']].[AutoScalingGroupName, MinSize, MaxSize,DesiredCapacity]" --output table
# 노드 4개로 축소
aws autoscaling update-auto-scaling-group --auto-scaling-group-name ${ASG_NAME} --min-size 4 --desired-capacity 4 --max-size 4
aws autoscaling describe-auto-scaling-groups --query "AutoScalingGroups[? Tags[? (Key=='eks:cluster-name') && Value=='siyoung-eks']].[AutoScalingGroupName, MinSize, MaxSize,DesiredCapacity]" --output table
# 삭제
helm uninstall cluster-proportional-autoscaler
kubectl delete -f cpa-nginx.yaml
5.4 도전과제
도전과제EKS addon 중 coredns 를 테라폼 배포 시, autoscaling 정책을 적용해보자
EKS에서 제공되는 CoreDNS add-on은 클러스터 규모에 비례하여 파드 개수를 스스케일링하는 기능을 지원합니다. Linear 모드로 작동하며 CPU 코어 256개당 1개 또는 노드 16개당 1개의 기준 중 더 큰 값을 따라갑니다. 계산방식은 다음과 같습니다.
Replicas = clamp(max(ceil(core 수/256), ceil(node 수/16)), min, max)
Optional Configuration settings의 autoScaling 항목에서 최소/최대 Replica의 범위를 지정해 운영할 수 있습니다. 아래 명령어로 EKS CoreDNS Add-on의 스키마를 확인해볼 수 있습니다.
aws eks describe-addon-configuration --addon-name coredns --addon-version v1.13.2-eksbuild.4 --query "configurationSchema" --output text | jq
{
  "$ref": "#/definitions/Coredns",
  "$schema": "http://json-schema.org/draft-06/schema#",
  "definitions": {
    "Coredns": {
      "additionalProperties": false,
      "properties": {
        "affinity": {
          "default": {
            "affinity": {
              "nodeAffinity": {
                "requiredDuringSchedulingIgnoredDuringExecution": {
                  "nodeSelectorTerms": [
                    {
                      "matchExpressions": [
                        {
                          "key": "kubernetes.io/os",
                          "operator": "In",
                          "values": [
                            "linux"
                          ]
                        },
                        {
                          "key": "kubernetes.io/arch",
                          "operator": "In",
                          "values": [
                            "amd64",
                            "arm64"
                          ]
                        }
                      ]
                    }
                  ]
                }
              },
              "podAntiAffinity": {
                "preferredDuringSchedulingIgnoredDuringExecution": [
                  {
                    "podAffinityTerm": {
                      "labelSelector": {
                        "matchExpressions": [
                          {
                            "key": "k8s-app",
                            "operator": "In",
                            "values": [
                              "kube-dns"
                            ]
                          }
                        ]
                      },
                      "topologyKey": "kubernetes.io/hostname"
                    },
                    "weight": 100
                  }
                ]
              }
            }
          },
          "description": "Affinity of the coredns pods",
          "type": [
            "object",
            "null"
          ]
        },
        "annotationTopologyMode": {
          "description": "Topology mode for annotations",
          "enum": [
            "Disabled",
            "Auto"
          ],
          "type": "string"
        },
        "autoScaling": {
          "additionalProperties": false,
          "description": "autoScaling configurations",
          "properties": {
            "enabled": {
              "default": false,
              "description": "the option to enable eks managed autoscaling for coredns",
              "type": "boolean"
            },
            "maxReplicas": {
              "description": "the max value that autoscaler can scale up the coredns replicas to",
              "maximum": 1000,
              "minimum": 2,
              "type": "integer"
            },
            "minReplicas": {
              "default": 2,
              "description": "the min value that autoscaler can scale down the coredns replicas to",
              "maximum": 1000,
              "minimum": 2,
              "type": "integer"
            }
          },
          "required": [
            "enabled"
          ],
          "type": "object"
        },
        "computeType": {
          "type": "string"
        },
        "corefile": {
          "description": "Entire corefile contents to use with installation",
          "type": "string"
        },
        "nodeSelector": {
          "additionalProperties": {
            "type": "string"
          },
          "type": "object"
        },
        "podAnnotations": {
          "properties": {},
          "title": "The podAnnotations Schema",
          "type": "object"
        },
        "podDisruptionBudget": {
          "description": "podDisruptionBudget configurations",
          "properties": {
            "enabled": {
              "default": true,
              "description": "the option to enable managed PDB",
              "type": "boolean"
            },
            "maxUnavailable": {
              "anyOf": [
                {
                  "pattern": ".*%$",
                  "type": "string"
                },
                {
                  "type": "integer"
                }
              ],
              "default": 1,
              "description": "maxUnavailable value for managed PDB, can be either string or integer; if it's string, should end with %"
            },
            "minAvailable": {
              "anyOf": [
                {
                  "pattern": ".*%$",
                  "type": "string"
                },
                {
                  "type": "integer"
                }
              ],
              "description": "minAvailable value for managed PDB, can be either string or integer; if it's string, should end with %"
            }
          },
          "type": "object"
        },
        "podLabels": {
          "properties": {},
          "title": "The podLabels Schema",
          "type": "object"
        },
        "replicaCount": {
          "type": "integer"
        },
        "resources": {
          "$ref": "#/definitions/Resources"
        },
        "tolerations": {
          "default": [
            {
              "key": "CriticalAddonsOnly",
              "operator": "Exists"
            },
            {
              "effect": "NoSchedule",
              "key": "node-role.kubernetes.io/control-plane"
            }
          ],
          "description": "Tolerations of the coredns pod",
          "items": {
            "type": "object"
          },
          "type": "array"
        },
        "topologySpreadConstraints": {
          "description": "The coredns pod topology spread constraints",
          "type": "array"
        },
        "trafficDistribution": {
          "description": "Traffic distribution preference for routing to topologically closer endpoints. PreferSameZone routes to endpoints in the same zone; PreferSameNode routes to endpoints on the same node. If unset, uses default routing strategy.",
          "enum": [
            "PreferSameNode",
            "PreferSameZone",
            "PreferClose"
          ],
          "type": "string"
        }
      },
      "title": "Coredns",
      "type": "object"
    },
    "Limits": {
      "additionalProperties": false,
      "properties": {
        "cpu": {
          "type": "string"
        },
        "memory": {
          "type": "string"
        }
      },
      "title": "Limits",
      "type": "object"
    },
    "Resources": {
      "additionalProperties": false,
      "properties": {
        "limits": {
          "$ref": "#/definitions/Limits"
        },
        "requests": {
          "$ref": "#/definitions/Limits"
        }
      },
      "title": "Resources",
      "type": "object"
    }
  }
}
테라폼 실습 코드에 configuration_values를 추가해주었습니다.
- 테라폼 코드 예시